About
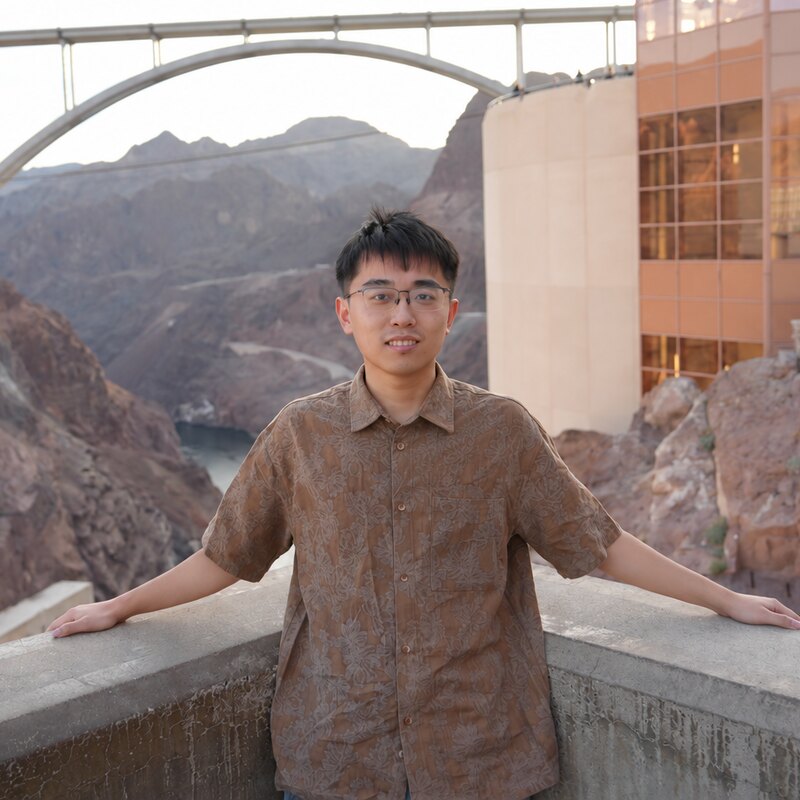
Hi there! I'm a PhD student at Purdue University  , Department of Mathematics, working in Prof. Guang Lin's research group. My research focuses on post-training of large generative models, including LLMs and diffusion models, through principled reinforcement learning and preference alignment. I received my B.S. in Mathematics and Applied Mathematics from the University of Chinese Academy of Sciences
 .
Research Interests
-
LLM Post-Training
Reinforcement Learning, RLHF, Preference Optimization, and Reasoning.
-
Generative Model Alignment
KL-Regularized Reward Fine-Tuning, One-Step Diffusion Generators, and VLA Policies.
Open to collaborations! Feel free to reach out if our research interests align.
News
- Oct 2026
Two papers were accepted to NeurIPS 2026.
- Jun 2026
Junyi serves as a co-mentor for Purdue SURF 2026.
- May 2026
Our paper on one-step generator RL (DIDR) was released, with models and a demo on Hugging Face.
- 2026
Junyi serves as reviewer for NeurIPS 2026.
Publications * equal contribution
4 papers
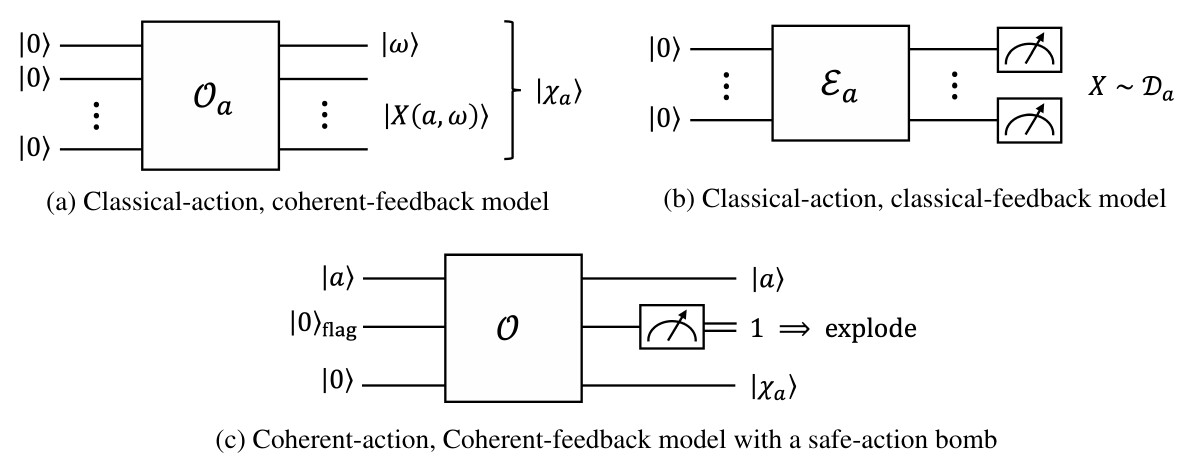
NeurIPS 2026
Quantum Safe Stochastic Linear Bandits
Constrained Thompson sampling with high-probability action feasibility and polylogarithmic regret under coherent quantum feedback.
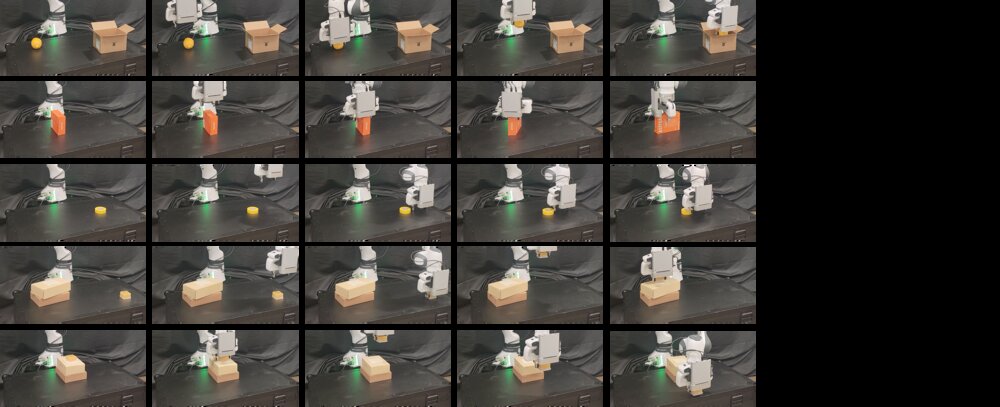
Preprint 2026
COCOA: Action Correction for VLA Policies via Supervised Fine-Tuning and Preference Optimization
An action-conditioned correction policy that repairs a frozen VLA's proposed actions, trained with SFT followed by Flow-DPO-style preference optimization.
GitHub
Loading repositories…
Education
Ph.D. in Mathematics, Purdue University
Advisor: Prof. Guang Lin

B.S. in Mathematics and Applied Mathematics, University of Chinese Academy of Sciences
Academic Services
Conference Reviewer
NeurIPS 2026
Mentoring
Purdue SURF 2026